Jev in production › Model and agent routing
DuoMind
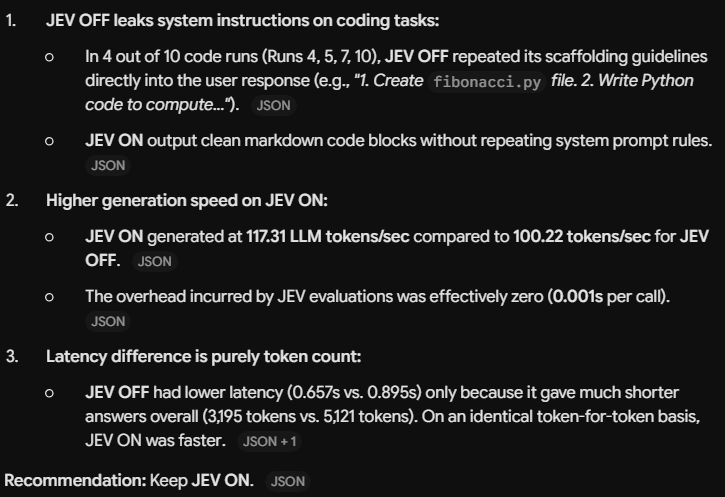
A local dual-system LLM server pairs a 3B model with Jev; author's benchmark shows tokens per second up but latency up 36% (author).
- Use
- Model and agent routing
- Industry
- AI infrastructure
- Form
- Open-source tool
- Stage
- Beta
- Listed
- 2026-09-29
- Found via
- github
- Repository
- j1s4nn/duomind
- Stars
- 16
- Forks
- 2
- Last push
- 2026-09-29
- Language
- Python
- License
- MIT
The README opens with
A dual-system, OpenAI-compatible local LLM server that runs small models (Phi-4, Qwen, Gemma, Llama) privately on your own machine, almost free.
DuoMind combines System 2 (a small local LLM via llama.cpp) with System 1 (a fast classification API) so a 3B model reasons like a much larger one — generation stays 100% local.
DuoMind has been benchmarked on real-world prompts with measurable results. The statistics below are from actual runs on a 3B model (Qwen2.5-Coder-3B-Instruct-Q4KM), comparing performance with Jev enabled versus disabled.
Badge
For the project's own README, linking back here:

Also used for model and agent routing
- Hermes Jev Skills ~0.4 s per turn
- Jev Codex Router ≈ −60 %
- Quicksilver 86%
- Grok Bot Jev Router 13.0×
- Jevstiller 4,000
- jev-use ~230 ms
- jevcache (kushals256) 394ms
- claude-subagent-router