Jev in production › Model and agent routing
jevcache (kushals256)
Local OpenAI-compatible proxy in which Jev judges whether a new prompt has the same intent as a cached one and serves the stored answer on a match, failing open to the model. A Jev-confirmed hit returned in 394ms, against 3244ms for a miss (author).
- Use
- Model and agent routing
- Industry
- AI infrastructure
- Form
- Open-source tool
- Stage
- In production
- Listed
- 2026-09-22
- Found via
- github
- Repository
- kushals256/jevcache
- Stars
- 12
- Forks
- 0
- Last push
- 2026-11-04
- Language
- TypeScript
- License
- MIT
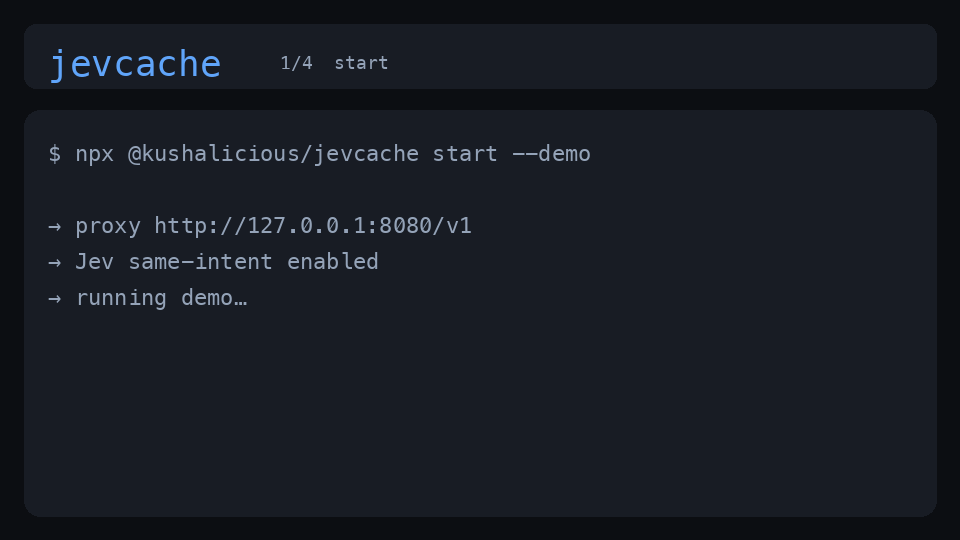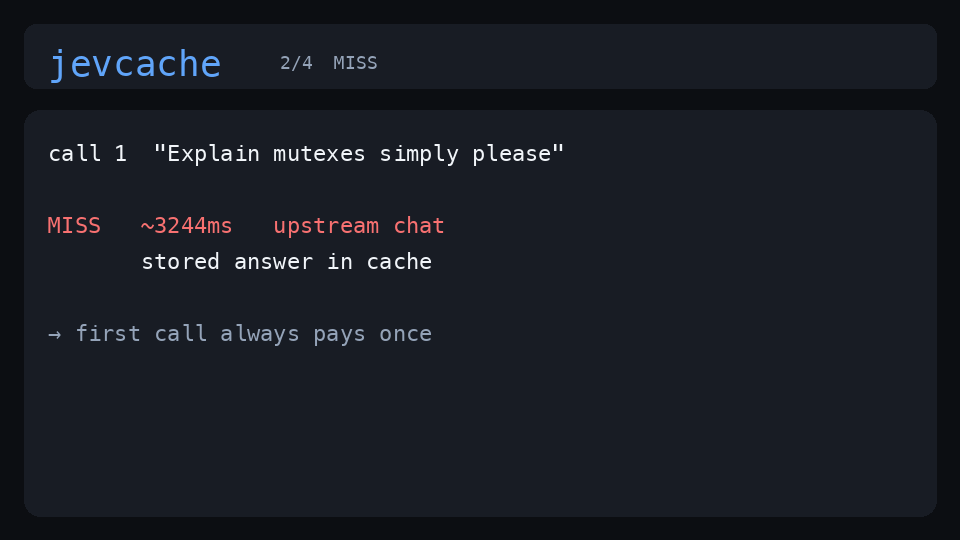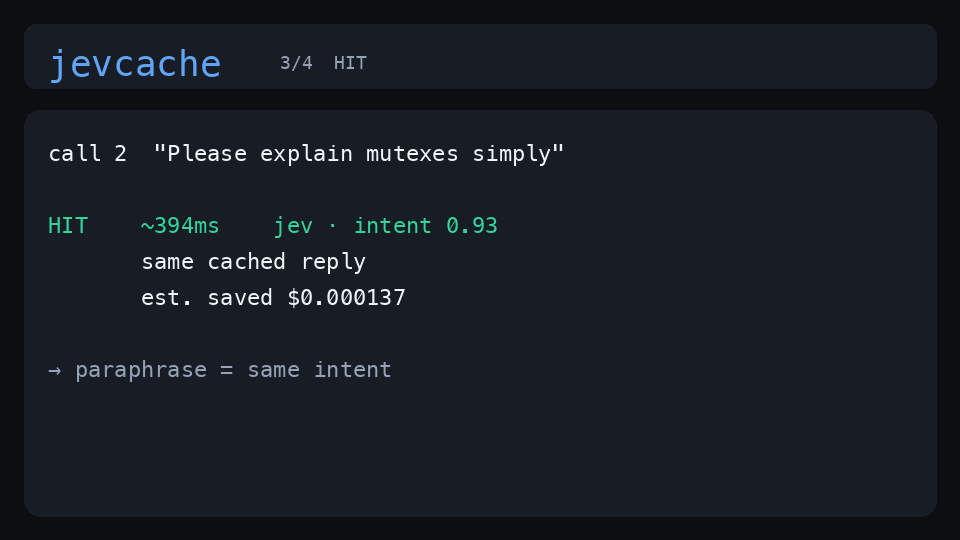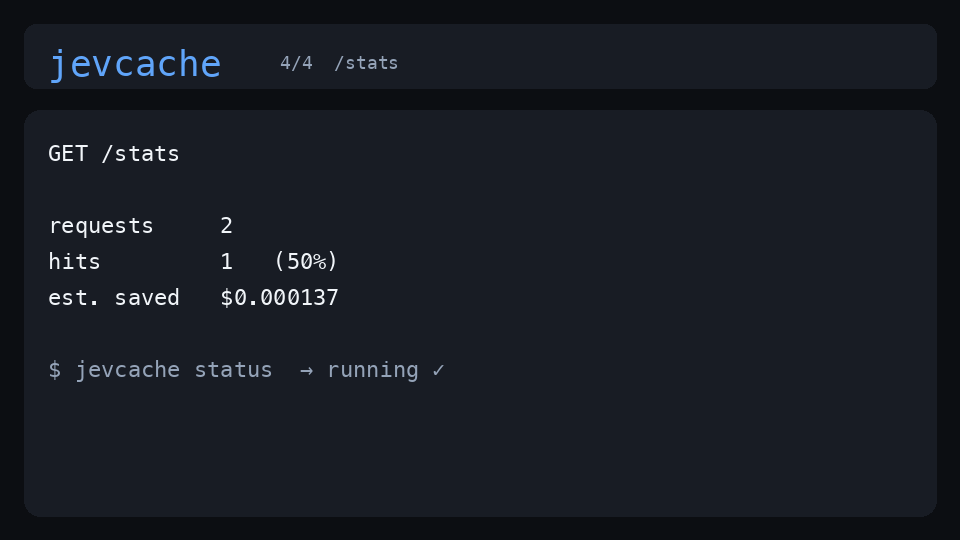
The README opens with
MorrowCache — routers pick a model. This proxy decides whether to call one.
An open-source semantic cache for OpenAI-compatible LLM APIs: run it locally, change your client's baseURL, and repeated or rephrased questions (and AI agent retries) are answered from cache instead of calling the model again.
npm package and CLI stay @kushalicious/jevcache / jevcache (download history unchanged). Site: morrowcache.vercel.app. Agent summary: https://morrowcache.vercel.app/llms.txt
Badge
For the project's own README, linking back here:
Also used for model and agent routing
- Hermes Jev Skills ~0.4 s per turn
- Jev Codex Router ≈ −60 %
- Quicksilver 86%
- Grok Bot Jev Router 13.0×
- JevAgentHarness 74
- jev-use ~230 ms
- Jevstiller 4,000
- ego-decision-layer 434ms