Jev in production › SQL and data pipelines
jevgrep
jevgrep asks Jev one yes/no question per piped log or text line and prints the lines whose yes probability clears a threshold, fast enough for tail -f. On its hand-labelled benchmark it scored a mean F1 of 0.90 against 0.87 for Claude Haiku 4.5 (author).
- Use
- SQL and data pipelines
- Industry
- IT operations
- Form
- Open-source tool
- Stage
- In production
- Listed
- 2026-09-22
- Found via
- discord
- Repository
- allebee/jevgrep
- Stars
- 2
- Forks
- 0
- Last push
- 2026-09-21
- Language
- Python
- License
- MIT
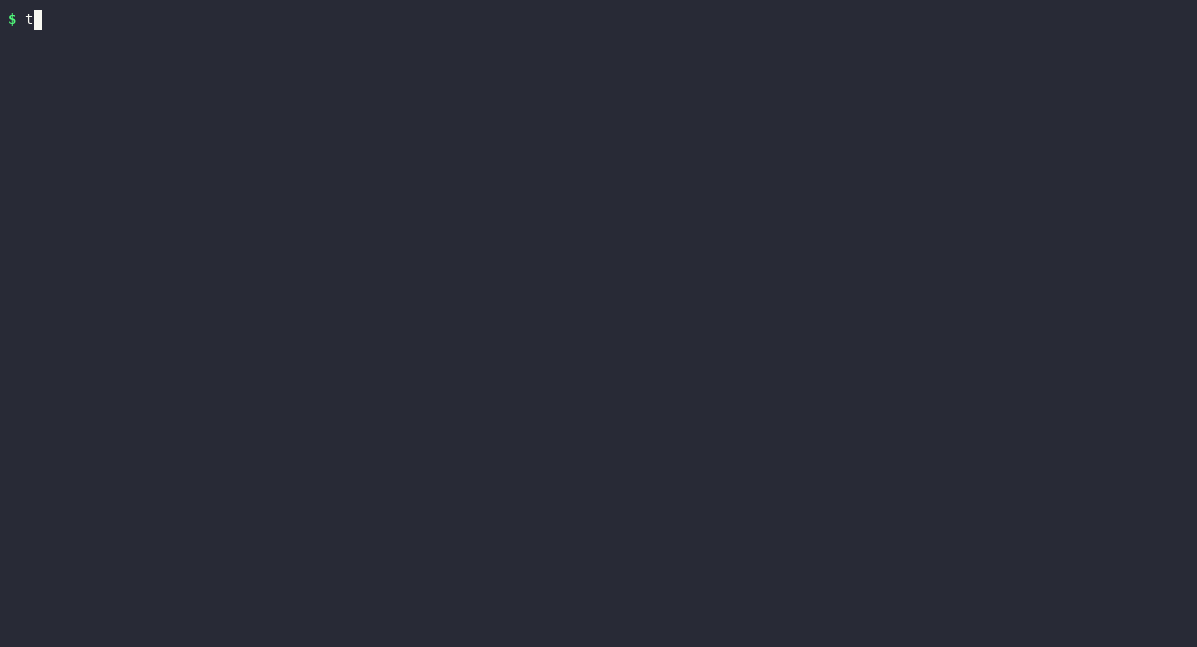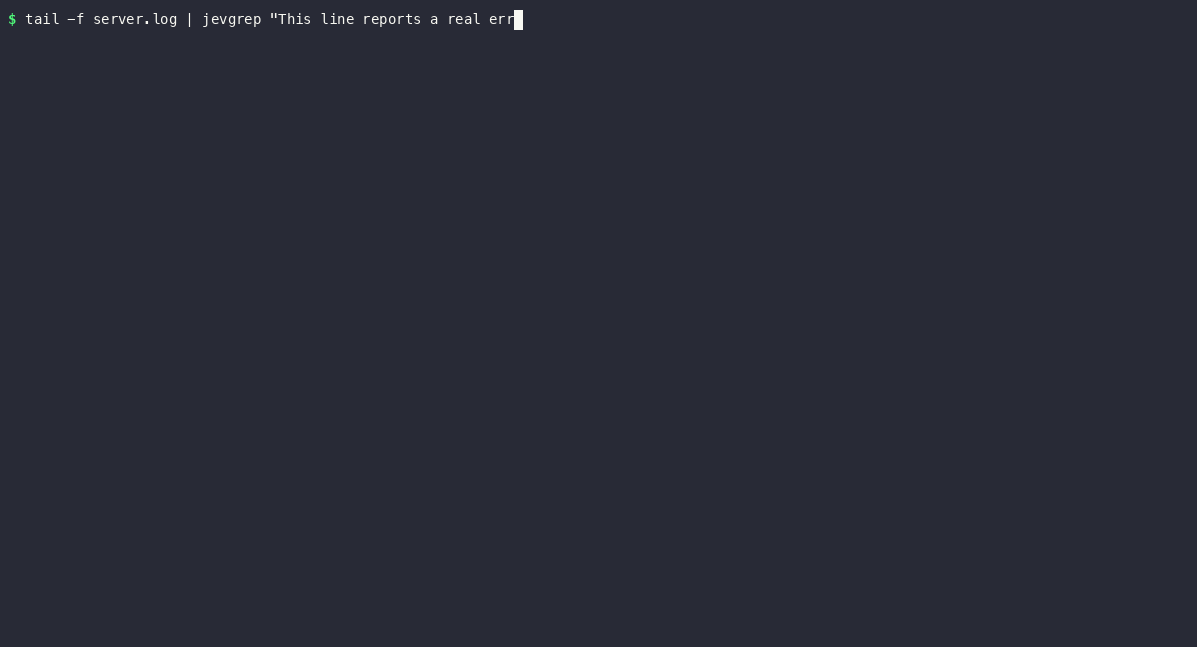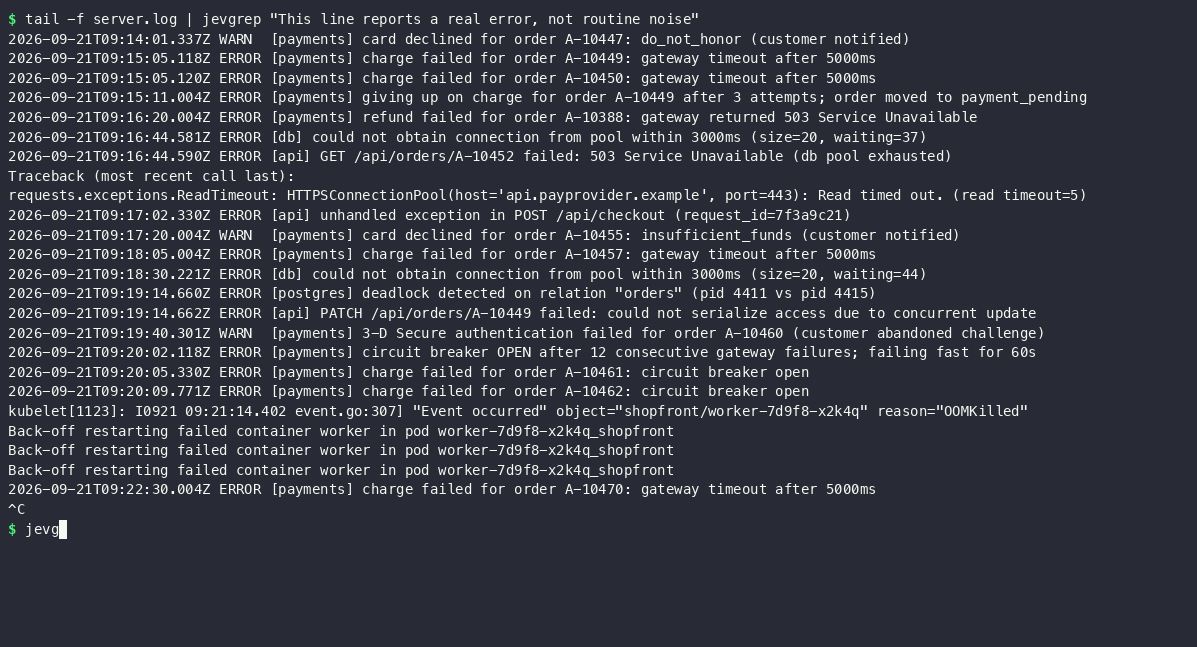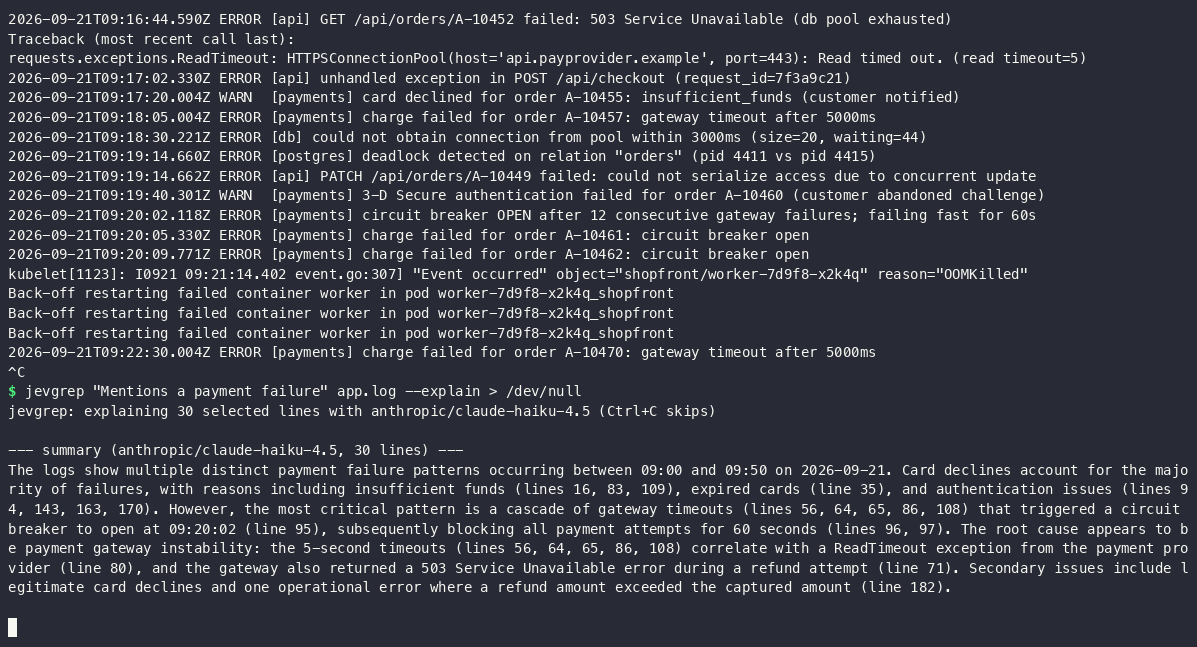
The README opens with
grep by meaning. Pipe in any text, ask a yes/no question in plain English, and get back only the lines where the answer is yes.
- Filters by meaning, not keywords. On the benchmark log, it kept the 503 access-log line, the Traceback and the OOMKilled event, none of which contain "error". It dropped errorrate=0.00, 0 failed payments and error handler registered. - Fast enough for a pipe. A match shows up about 0.7 s after the line is written, so it works behind tail -f, kubectl logs -f or journalctl -f. - Cheap. About $0.004 per 1,000 lines. On the benchmark that is 46× cheaper than Claude Haiku 4.5 and 170× cheaper than Claude Sonnet 5, with a mean F1 of 0.90 against their 0.87 and 0.95. - Behaves like grep. It supports -v, -n, --json and pipes,...
Badge
For the project's own README, linking back here:

Also used for sql and data pipelines
- JevSDSQL $0.389
- grev sub-cent cost per few thousand lines
- Jev IDS 7.7x
- jev-harness (AntonioCoppe) 1.3 seconds
- jev-ultralightspeed 41% less money
- jlink $2.95
- signal-weave 130/144 exact outcome decisions
- Vibefilter 1,000 rows in about a second