Jev in production › Agent context and memory
jevtrim
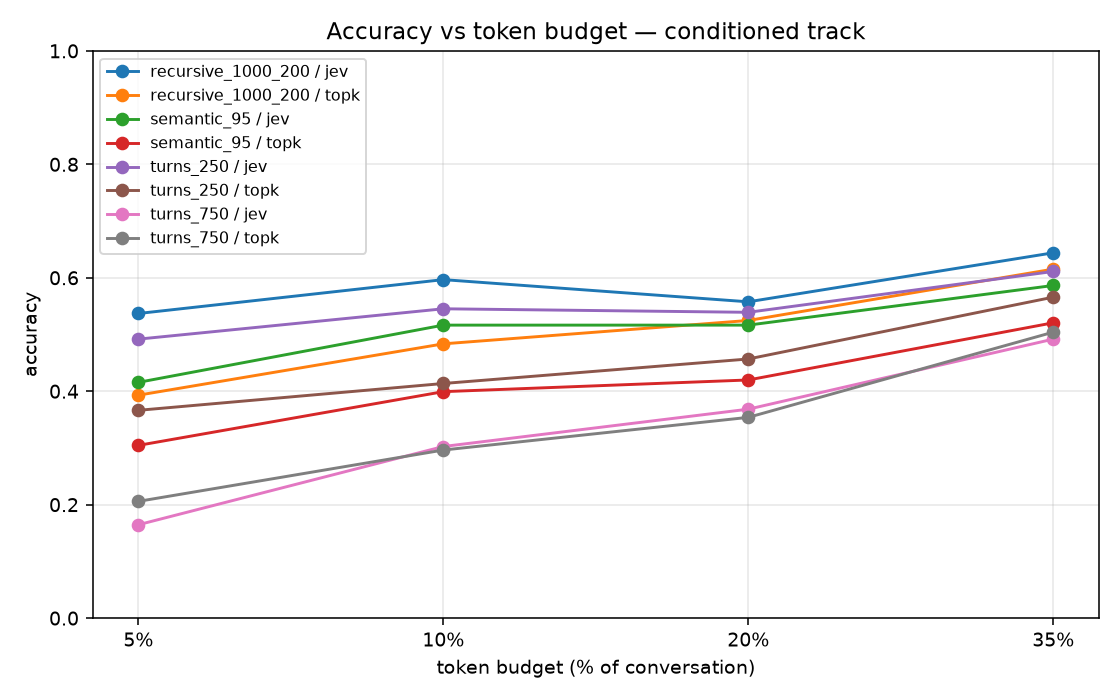
Benchmarks Jev as a context-compaction judge against retrieval and summarization on LoCoMo, across 486 questions over 10 conversations (jevtrim).
- Use
- Agent context and memory
- Industry
- AI infrastructure
- Form
- Open-source tool
- Stage
- In production
- Listed
- 2026-09-25
- Found via
- github
- Repository
- pdrpinto/jevtrim
- Stars
- 5
- Forks
- 0
- Last push
- 2026-09-25
- Language
- Jupyter Notebook
- License
- MIT
The README opens with
A comparative analysis on context compaction driven by calibrated judgements instead of summarization. Jev scores every chunk of a conversation for relevance to what is being asked, ordinary Python keeps the chunks that fit a token budget, and the result is auditable, deterministic and replayable offline.
Built on Jev (typesafe/jev-1.13), TypeSafe's System One decision model, reached through OpenRouter.
Left: accuracy against the token budget, conditioned track, 486 questions over 10 conversations. Right: answering with only the evidence (turn or chunk) scores below the best method.
Badge
For the project's own README, linking back here:

Also used for agent context and memory
- MemSearch (Zilliz) 4.70 percentage points
- Code Puppy 90%
- RikkaHub Plus 华灯版 ~100ms end to end
- Enzyme 350x
- Hermes Tool Slimmer 4.3k
- Jev Recall (samdotmak) 17/18
- pi-jev-skill-picker 87.9%
- Astra (MatrixOrigin)