Worth asking?
A typed-decision model was wired into five places in a Dungeons & Dragons co-DM. This is the measurement of whether it earns its place — against the code it replaces, and against a frontier model doing the same job.
What was actually tested
A showcase would list what the model can do. This is the other thing: for each judgement, what did the code do before, what does Jev do, and what does a frontier model do, on the same items, scored against the same answer key.
Three arms, every time:
The rule that shipped before: a regular expression, a path rule, or in two cases nothing at all.
Called through the product's own question builders and batching, not a harness written to flatter it.
A frontier model called as a classifier — batched, thresholded, given the same information and nothing more.
The answer keys were written blind. Whoever labelled a set was forbidden from calling Jev while doing it, and from importing the provider at all. A benchmark whose author has seen the system's answers is a description of that system, not a test of it.
Each set was then audited by a separate reviewer whose standing assumption was that the benchmark had been rigged, and whose first job was to compute what a trivial baseline scores. That matters more than it sounds: on the table-rule set, answering “clean” to everything scores 90.8% accuracy. Accuracy is a junk headline here. Recall is the number.
Table rules: 19% to 88% of violations caught
94 paragraphs — 68 clean ones that shipped to a real table, 26 written to break exactly one of the three table rules, 51 of the 94 marked hard by the labeller. The rules: never narrate a player's character, never tell the DM when to roll, never end a sentence explaining what a look means.
| Arm | Recall | Precision | False alarms | |
|---|---|---|---|---|
| A — incumbent regex | 19.2% | 5/26 |
100% | 0 |
| B — Jev, mean of 8 runs | 88.0% | ±6 |
95.4% | 9 in 2,048 |
| C — gpt-5.6-sol, called as a classifier | 96.2% | 25/26 |
56.8% | 19 in 256 |
A fourth arm was thrown away. An Opus agent judging each item by hand scored 26 of 26 — and should be ignored, because the audit found it had read the answer key's own labelling notes and each item's provenance tag before judging. Provenance alone separates the 56 guaranteed negatives. That is not a measurement of a frontier model, it is a model agreeing with a key it had seen, and it has been removed from this page rather than quoted as a ceiling.
This table was wrong when it was first published, and the correction is the most useful thing on the page. The first version reported Jev at 96.2% recall and 100% precision from a single run. An adversarial re-read pointed out that all the runs had reused one item order, so the result was one draw rather than an expected value. Re-run eight times with the order shuffled: precision averages 95.4% (92.3 to 100, reaching 100 in one run of eight) and recall averages 88.0% (80.8 to 92.3). Re-running the original order returned 88.5% rather than the published 96.2%, so the variance is the model, not the shuffle.
Nine false positives across 2,048 negative judgements, concentrated in three paragraphs that straddle the 0.70 line. Jev is not deterministic, and anything built on it should assume a couple of points of movement between runs.
What is left is the comparison that describes a shipped system: a frontier model called the way you would actually call one — batched, thresholded, asked for a number. It gets better recall than Jev, and then raises 19 false alarms in 256, thirteen of them on the hardest rule, against Jev's 9 in 2,048.
A checker that cries wolf on one paragraph in five stops being read. That is the trade on offer: against the deployable frontier classifier Jev gives up about eight points of recall and buys back roughly forty points of precision.
The reason is not that the regex is badly written. It is that for one of the three rules no regex was ever written. Nobody could think of one. “Does this paragraph move a player's character?” has no surface form to match on, so that rule went unchecked from the day it was made a rule until the day it was asked as a question. The incumbent scores 0 of 9 on it by construction, not by accident.
Routing: the incumbent puts half of everything in one bucket
90 messages typed at the assistant, labelled with the lane a reasonable co-DM should run.
| Arm | Overall | “chat” precision | Not-a-game-message | |
|---|---|---|---|---|
| A — incumbent regex | 36.7% | 33/90 |
0.26 | cannot express it |
| B — Jev | 87.8% | 79/90 |
0.74 | 11 of 11 |
The incumbent's failure has a shape: 45 false positives on a single lane. When no keyword matches, everything lands in “talk”. And it has only four lanes, so a message that is not about the game at all — a billing question, an attempt to talk the assistant out of its own instructions — has nowhere to go. On the fair four-lane subset, where that handicap is removed, it is still 41.8% against Jev's 86.1%.
This is the result that held up best under attack, and it is stronger than it first looked. Jev strictly dominates here: across all 90 messages there is not one the incumbent gets right and Jev gets wrong (46 the other way, p = 2.8×10⁻¹⁴). Re-run live it returned the same 90 of 90 per-item predictions — on this task, unlike the table rules, it is effectively deterministic. And it survives hostile relabelling: flip every ambiguous item to its declared alternative and the gap is still 34.4% against 74.4%.
One thing this does not show. A draft of this page implied the incumbent was dangerous with prompt injections. It is not, on this evidence: it routed 0 of the 11 account and injection messages into a lane that writes anything. It put them in chat and lookup — wrong, but harmless. The hazard is real in principle and was not observed here.
Contradictions: nothing was checking before
60 statements written against the real canon of eight factions, each scored against the eight facts already on file for that faction. Here the incumbent is not a weak rule, it is nothing — the database returned the adjacent facts and a human read them. So the benchmark built the cheapest thing that could have been written instead: token overlap plus a polarity cue, with its threshold tuned on this very set, scored in its own favour.
| Arm | Accuracy | Precision | Hard subset | |
|---|---|---|---|---|
| incumbent — no check existed | 51.7% | base |
n/a | 52.8% |
| tuned lexical baseline | 66.7% | 0.66 |
0.655 | 61.1% |
| Jev | 96.7% | 27/29 |
1.00 | 94.4% |
The 51.7% is not a score, it is the base rate of never ruling — which is what happens today. And the ranking is the part a person feels: the colliding fact comes back first 86.2% of the time and in the top three 96.6%, against an expected 4.3 rows read in arbitrary order.
Where it is weak, and it matters. At the level of which fact collides, precision falls to 0.684 — it is reliable about something here contradicts and names an extra innocent fact roughly a third of the time. And the item-level 1.00 precision will not survive contact: this set is about half contradictions by construction, where real proposals are mostly compatible, so the figure flatters. Treat it as a ranker worth reading first, not as a gate.
What it costs, honestly
Jev publishes no price. co-dm's meter knows this and refuses to invent one: its spend is recorded in tokens, kept out of the dollar total, and the summary marks itself incomplete rather than reporting a total that is missing a line. So no table here says “$X versus $Y”.
What can be said is what the errors cost. For routing, the classifier is not where the money is — the incumbent is a local pure function at microsecond latency and zero marginal cost, and on the call alone it wins by construction. The money is in the turn that runs afterwards in the wrong lane.
| Arm | Guide turns wasted | Guide turns redone | Cost of being wrong |
|---|---|---|---|
| A — incumbent regex | 2 | 17 | $2.62 |
| B — Jev | 0 | 4 | $0.56 |
$0.023 saved per message routed, against roughly $0.0005 to ask — about 46 times its own cost in turns that would otherwise have run in the wrong lane.
That dollar column is a model, not a meter reading. No turn was executed in this run. It prices a missed guide request as one wasted cheap turn plus one full rebuild, at the $0.1235 an Opus guide turn actually cost across 29 metered calls. If the DM notices and rephrases, it costs less; if a wrong guide reaches the table it costs something other than money.
The same result without any pricing assumption, in the unit the benchmark itself measures: the incumbent starves 36 turns of their proper output budget against Jev's 8, and the tokens Jev spends deciding are about 3.7× less than the budget shortfall it avoids.
Speed: the whole guide in under a second
Quoted as serial call time on both sides, because that is the honest comparison. Run with six calls in flight, Jev finishes the guide in 773 ms of wall clock, but that is throughput rather than latency and the frontier arms were not given the same concurrency. Like for like it is 4.2 s against 131 s, about 31×. What a person actually waits for is one batch: 751 ms.
| Arm | Answered | Wall clock | Output tokens | Cost |
|---|---|---|---|---|
| Jev | 94/94 | 4.2s | 6,198 | no published price |
| gpt-5.6-sol | 94/94 | 131.5s | 8,209 | $0.0851 |
| gemini-3.8-flash | 62/94 | 184.2s | 28,845 | $0.1147 |
| deepseek-v4.1-flash | 32/32 (subset) | 284.5s | 11,231 | $0.0072 |
Every other model had to write its reasoning out before it could answer, and the clock shows it: 20 to 33 seconds per batch of sixteen for the fastest of them, 191 seconds for a single batch of the cheapest. Jev writes a number, and a batch of sixteen comes back in about three quarters of a second.
The cheapest arm is also the clearest illustration of why price per token is the wrong lens.
deepseek-v4.1-flash costs a twelfth of what gpt-5.6-sol costs and
took more than twice as long for a third of the work.
That is also why the shipped code runs both: the regexes cost 3.5 ms for all 94 paragraphs and catch five real violations, so they go first, and the judge is asked only about what is left.
Where it loses
-
It is not deterministic, and the first version of this page hid that
Eight runs over the same 94 paragraphs, shuffled, moved recall between 80.8% and 92.3% and precision between 92.3% and 100%. The published figures came from a single run and were the best draw in the set. Anything built on this should carry a couple of points of slack and should not quote a single run as a capability.
-
The frontier ceiling was never actually measured
The arm meant to establish it —
claude-opus-5reading each item and reasoning — scored perfectly on both judgements and turned out to have seen the answer key's own notes and each item's provenance before judging. It has been discarded, not quoted. So this page cannot say how good a careful frontier model would be, only how good one behaves as a deployable classifier, which is 56.8% precision against Jev's 95.4%. Establishing the real ceiling needs an uncontaminated run that has not been done. -
The incumbent is partly being charged for a rule nobody wrote
9 of the 26 violations test rule 1, which has no incumbent instrument at all, so those are automatic misses and the 19.2% headline flatters the comparison. Restricted to the 85 items whose rules the regexes actually implement, the incumbent still only reaches 29.4% recall. The gap narrows and does not close.
-
The answer key shares an operationalisation with the thing it grades
The labeller wrote the key against the literal wording of each rule — which is also close to the wording Jev is given in the question. Where that reading of a rule is wrong, both are wrong together and the benchmark scores it correct. Fifteen negatives are marked contested for this reason, and two of the three paragraphs that ever produced a false positive are among them. The routing set has the same shape: its labels were written from the same lane descriptions Jev reads, so 87.8% is a measure of following that rubric, not of routing being right in some absolute sense. The DM who owns these rules has reviewed neither key.
-
Two no-content shortcuts beat the incumbent
On the table-rule set, “flag anything under 160 characters” scores 81.9% and “flag anything that was authored rather than taken from the guide” scores 87.2% — both above the incumbent's 77.7%, both reading nothing. That is a property of the set, not of the incumbent: the authored violations are shorter than the real paragraphs. Jev is not riding it, holding 97.9% on a length-matched slice where the trivial baseline is 44.7%, but a set that a ruler can beat is a set to rebuild.
-
The cheap models are slow, not broken — and that is worse than it sounds
A single-paragraph probe had
deepseek-v4.1-flashspending 1,500 output tokens and emitting nothing, which looked like a hard failure. Re-measured over 32 items it answered all 32 cleanly, so that first read was wrong. What is true is the clock: 284 seconds for 32 paragraphs, about 8.9 seconds each, which puts one session guide at a quarter of an hour.gemini-3.8-flashwas worse in a different way — 184 seconds, 28,845 output tokens, and two of its six replies were malformed JSON, so 32 of the 94 paragraphs never got an answer at all.That is the hidden cost of a model that answers in prose: the reply has to be parsed, and parsing can fail. Jev's answer is typed, so there is nothing to parse and no parse to fail. Across every run here it returned 94 of 94.
-
The answer key shares a blind spot with the thing it grades
The labeller flagged it: 56 of the 68 clean paragraphs were written by this same assistant under these same three rules. Any rule it systematically misreads is baked into the key as correct. Fifteen labels were marked contested for exactly this reason, and every arm scores 100% on that slice, which should be read as the slice being unable to separate them rather than as three perfect scores.
-
On the art library, the evidence currently argues against using it
The 287-of-300 figure below is a sample measurement, not a scored benchmark, and its ground truth comes from file names — which the incumbent path rule never sees, so that comparison is not neutral and is not claimed as one. A separate 177-row set was scored, and what it found is unflattering: a three-line rule that reads only the file extension beats the shipped path rule, and once the set is reweighted to the library's real composition — about 83% props — simply answering “other” to everything scores 0.83 against Jev's 0.77. On that judgement, at that prevalence, the model is not currently worth the call. It stays in proposals-only for a reason.
-
Fact triage is not benchmarked at all
A set exists; the run is unfinished. Nothing on this page claims it works.
The accident along the way
The art library holds 181,805 files sorted by the folder they sit in, 151,132 of them filed as tokens — the cut-out figures that stand on a battlemap. Three hundred were sampled and put to the model. Eight more, pulled by name from the same pile:
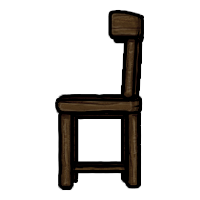
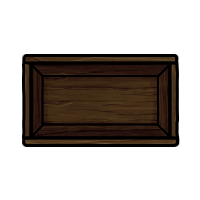
287 of the 300 were not tokens, at 0.91 average confidence. The useful part
was not the classification. It was that reading the paths behind the answers showed the cause
was ours: the library's own root is a folder named Assets and Tokens, and the
sorting rule handed that word down to every bracket and cushion inside it. Maps had been
protected from exactly this for months. Tokens never were.
One line of code, 59,345 files corrected, and no model in the fix — only in noticing. That is the second time in a day that asking a cheap judge about everything found a bug in code that was not the model's.
What is actually switched on
| Judgement | Shape | Benchmarked | Status |
|---|---|---|---|
| Table rules | yes/no ×3 | yes | Live. Regex first, judge on the rest, flags at 0.70. |
| Canon contradictions | yes/no | set built, run unfinished | Live. Sits on the database's answer before the writing model sees it. |
| Message sorting | choice | yes | Shadow only. Logs both answers, changes no routing. |
| Art library kinds | choice | not scored | Proposals only. Committing them is a separate step. |
| Fact triage | score ×2 | not scored | Ranking only. It promotes nothing to canon. |
Remove the key and all five switch off, and the assistant behaves exactly as it did before. That is the property that made this worth measuring rather than arguing about: the incumbent is still there, underneath, and it is still the thing that runs first.