Jev in production › Document and record classification
JevSpan
Jev classifies entity spans in a zero-shot NER model that averages 73.7 strict F1 across 12 benchmarks (company).
- Use
- Document and record classification
- Industry
- Education and research
- Form
- Open-source tool
- Stage
- Announced
- Listed
- 2026-09-28
- Found via
- github
- Repository
- lzq-0529/jev-span
- Stars
- 6
- Forks
- 1
- Last push
- 2026-09-28
- Language
- Python
- License
- MIT
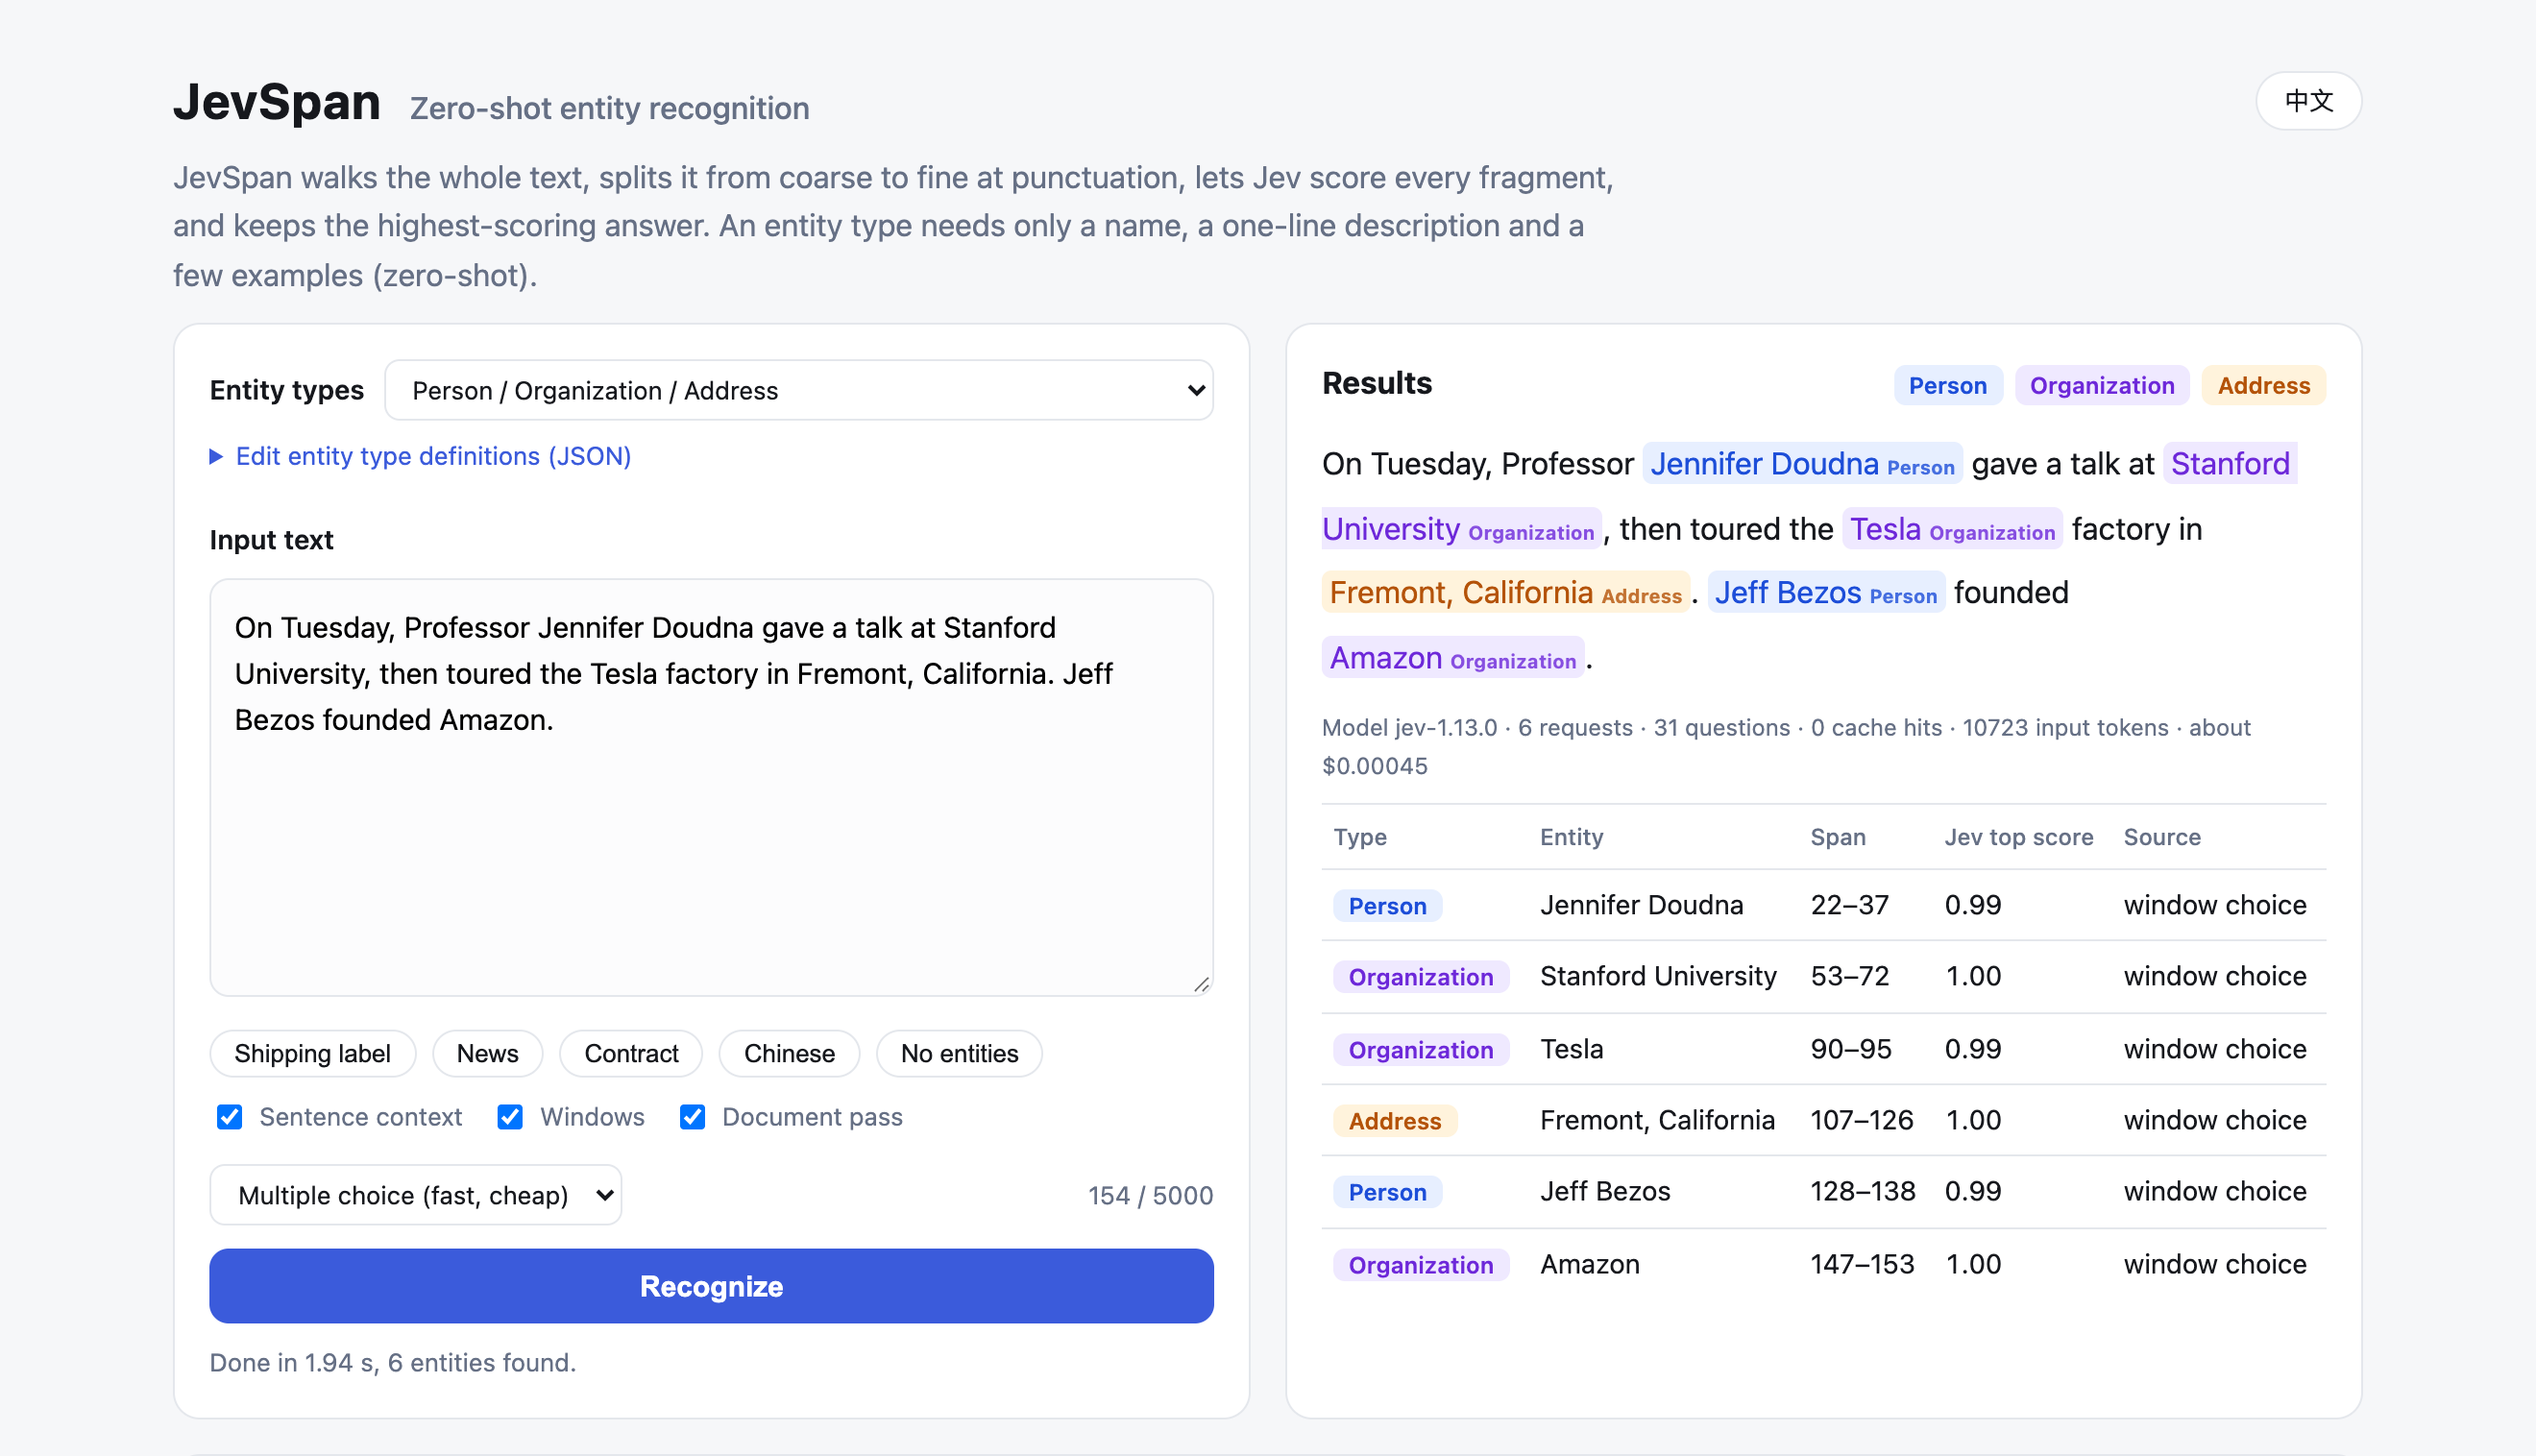
The README opens with
Zero-shot named entity recognition built on TypeSafe Jev. Describe your entity types in one line each. No training data, no GPU, no fine-tuning.
Jev answers typed multiple-choice questions with calibrated probabilities, but it never returns entity spans on its own. JevSpan turns it into an entity recognizer. It cuts text at punctuation, offers every candidate window to Jev as an option, verifies what Jev nominates, and then lets Jev settle the exact boundaries and type. Every entity comes back with a probability and a trace of the questions that produced it.
Badge
For the project's own README, linking back here:

Also used for document and record classification
- dailypaper-skills 99.47%
- Kyotofin tax-doc-classifier 34× cheaper
- LatteReview 0.2s
- JEV Paper Radar 96.9%
- PDF Race $0.0022
- Laser (Omarchy) about 1 cent per day
- Astrolabe 5,857
- Resurface 99%