Jev · jev-1.13.0 · shipping on this domain
743 nouls a posting
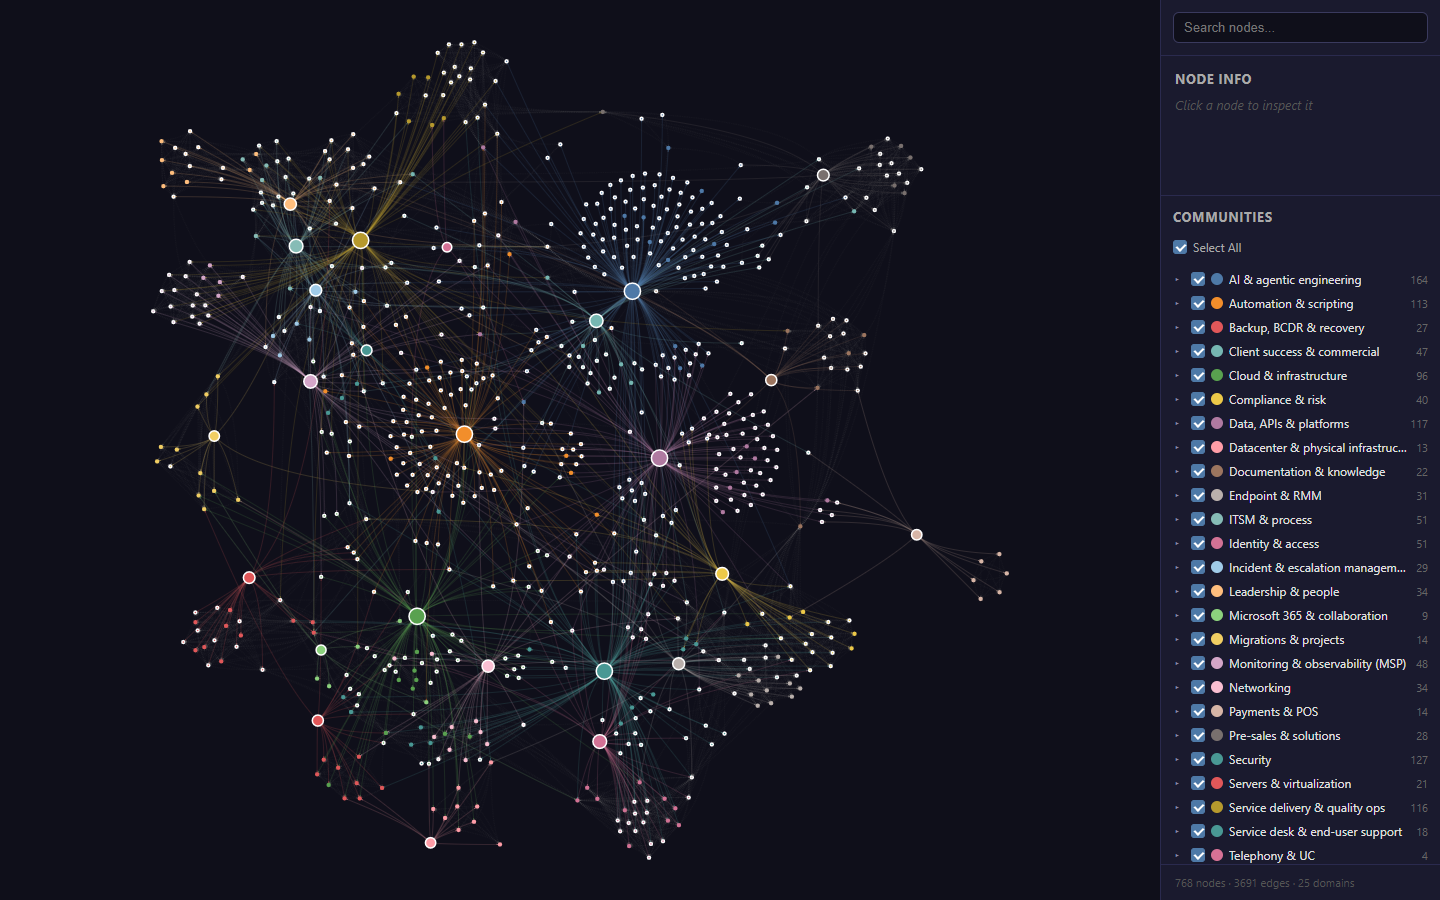
I catalogued seventeen years of work as 743 skills and asked Jev, once per skill, whether a given job posting calls for it. The whole sweep takes 9.3 seconds. Six things I measured on the way in — one of them contradicts the obvious reading of the docs.
out — 60 questions, one state
{
  "state": { "job_posting": "…" },   // 6.3 KB, sent once
  "model": "jev-latest",
  "questions": {
    "q0": {
      "type": "noul",
      "instructions": "Does this posting call for
        \"RMM\", either by name or by describing
        work that requires it?",
      "criteria": {
        "true":  "The posting asks for it…",
        "false": "The posting does not need it"
      }
    },
    "q1": { … 59 more … }
  }
}
back — typed, no parsing
{
  "answers": {
    "q0": { "noul": 0.99 },
    "q1": { "noul": 0.07 },
    …
  }
}

// No "return JSON only, no prose, no
// code fence". No regex over a reply.
// No retry when the fence comes back
// wrong on call 400.
//
// The other inference scripts in this
// repo do all three, and each fails in
// a new way every few hundred calls.
// That is the whole reason this work
// moved onto Jev.
Measured 17 Sep 2026 against a live NinjaOne solutions-engineer posting
Since writing this I benchmarked it properly — Jev against Haiku 4.5, GLM-5.3-flash, embeddings and a substring matcher over 8,916 decisions, plus 240 of the hardest pairs adjudicated twice. It wins latency, reliability and the judgement the tool actually makes — and the cost claim does not survive the token counts: Skill selection, measured ↗
Six things I measured
Each of these has a harness in the repo that produced it. Three changed my code. One made me withdraw advice I had already given somebody else.
“Keep the state small” is only half a rule
I started by sending 45 KB of career history as the state for every question. ConnectWise came back as named, no work behind it — against twelve years of running MSPs on it. Calls took minutes. Trimming to a few hundred relevant characters fixed the answer and took each call to 11 ms. So far, exactly what the docs warn about.
Then I trimmed a job posting the same way, and the answers got worse:
| State | Chars | Time | Mean shift | Answers moved ≥ 0.20 |
|---|---|---|---|---|
| full posting | 6,350 | 0.78s | baseline | — |
| requirements only | 2,614 | 0.49s | 0.045 | 1 |
| headline only | 700 | 0.51s | 0.223 | 11 of 30 |
At 700 characters, “primary escalation point for live-fire incidents” fell from 0.89 to 0.23 — on a posting about incident management. Starving the state produces confident wrong answers, which is worse than slow ones.
The rule I use now: is the state a haystack or the subject? A career history is a haystack — any one question touches a sliver of it, so the rest is noise and cutting helps enormously. A job posting is the subject — every question asked is about that document, so there is no irrelevant half to remove and trimming just deletes evidence. I have not found where the threshold turns over; 6.3 KB of subject was fine and 45 KB of haystack was not.
jev_state_size.py · 30 questions × 3 state sizes
It is not deterministic, and your thresholds are where that bites
Same 25 questions, same state, three runs: identical answers 4 times out of 25. Mean spread 0.015, largest 0.040. That is small enough to ignore right up until a cutoff acts on it — and mine sat at 0.15 and 0.60, which is exactly where the answers cluster. Roughly one item in twenty-five landed on a different side between runs with no input change and no way for a reader to tell that from a real one.
I found it because a refactor that changed no logic produced a different résumé. Anything a threshold touches now goes through a wrapper that averages several calls and returns the spread alongside the value, so a number sitting on a boundary is visible as one instead of silently flipping.
jev_determinism.py · 25 questions × 3 runs
The noul is bimodal. That is why the ladder is worth it — not stability
I switched some questions from noul to score expecting named rungs to be steadier than a float. They are not. Normalised, the ladder moves 0.047 against the probability's 0.040 — the same wobble in different units. A score returns a probability-weighted value across the rungs, not a rung, so it has just as much room to drift.
What it actually buys is spread. Over 244 facts on one posting the noul put 130 below 0.2 and only 5 above 0.8:
0.0noul, 244 facts1.0
Most answers pile up at “no,” so a threshold has to cut through the pile — which is the same thing finding 02 says is unstable. The ladder distributes across the range instead, so a cut lands in open space. Pick the primitive for its distribution, not for an intuition about stability.
jev_discrimination.py, jev_noul_vs_score.py, jev_dist.py
A choice with no covering option still answers, at full confidence
Given a fixed set that does not cover the input, it picks one anyway — and does so at maximum confidence. The usual mitigation, threshold the confidence and route the uncertain to a human, is therefore structurally blind to this failure: there is no low number to catch.
This was not academic for me. I had recommended replacing somebody's keyword intent router with a six-way choice. Reproducing the failure on their actual lanes showed the recommendation would have been a downgrade — the code it replaced already had a fallback. I withdrew it and sent the harness. If you use choice in production, put the escape hatch in the option set, not in a confidence gate downstream.
jev_escape_hatch.py, jev_codm_rubric.py
Referring to a value by path does not dereference it
Write the value into the question literally. A question that names skills[3].name instead of the string it holds gets read as that literal text, and the answer quietly changes: patch management scores 0.90 written in and 0.34 referenced. Nothing errors. You just get a worse number, everywhere, forever.
This cost me a full day because the scores were plausible. They were not obviously broken — they were mildly, consistently wrong, which is much harder to see.
Found by diffing two runs of infer_domains.py
It demotes well. It has never once rescued
I layered Jev over an existing keyword scorer with two arms. Demotion works: on one posting it correctly threw out commit counts, a multiplayer game, a company banking setup and a twenty-year-old call-centre job — all of which the substring test had scored as relevant. Ten demotions on that posting, seven on the next.
Rescue has never fired. Across three postings, the facts the lexical scorer dropped top out at 0.36, 0.56 and 0.43 against a 0.60 bar. Not one clears it. Jev agrees with the cheap test about what to throw away and disagrees about what to keep — so it earns its cost as a second opinion on inclusion, not as a recall net. I left the dead arm in, labelled, rather than lowering the bar until it fired.
jev_select.py, jev_dist.py · 3 postings
What it produces
One posting in, a ranked sheet out. wants is Jev; holds is the catalogue; the ranking multiplies them in code.
scored 743 skills in 9.3s (13 ms each)

  match  wants holds  skill                       alt  era
  0.89   0.98  0.85   demo environments           DTS  —
  0.84   0.92  0.85   PowerShell                  DT   —
  0.81   0.99  0.70   networking                  —    2005 to present
  0.81   0.99  0.70   pre-sales                   —    2014 to 2025
  0.78   0.95  0.70   documentation               —    2018 to present
  0.72   0.99  0.55   technical demonstrations    DTS  2009 to 2025

  wanted, and thinly held — know these before the interview:
    wants 0.99  holds 0.25  RMM
    wants 0.97  holds 0.25  RMM agent deployment
    wants 0.99  holds 0.10  endpoint management
    wants 0.98  holds 0.10  RMM and endpoint management at scale
The second list is the one that pays. A tailoring pass that only surfaces strengths tells me what I already knew; the gap list is what to read before the call, and the same run produces it for free.
The catalogue those holds come from is built the same way — a per-skill noul against each of 25 domains decides membership, and those memberships are what hold the published graph together. Before that pass ran, three domains connected to nothing at all.